The scorecard
Zendesk’s current reporting separates Unassisted conversations, Assisted escalations, Contained resolutions, and Verified resolutions. Build a scorecard that preserves these names rather than inventing a single “AI success” bucket.
| Metric | Question it answers | Check before acting |
|---|---|---|
| AR% | How much categorized AI work was contained or verified? | Same date range and post-May-18 definition |
| Verified resolutions | What consumed automated-resolution usage? | Ticket sample and cost/usage view |
| Contained resolutions | What did AI handle without follow-up? | Whether containment fits the customer outcome |
| Assisted escalations | Where did AI contribute but a person finished? | Repeated issue and routing pattern |
| Channel group | Does Digital behave differently from Voice? | Compare like with like |
Zendesk’s reporting change explains that AR% is (Contained + Verified) / all categorized outcomes. It may rise after the definition change, so do not claim that a new percentage alone proves a better agent.
Inspect the records, not just the total
For accounts on resolution allowances, open Admin Center > Account > Usage > Resolutions. Zendesk’s usage guide lets admins filter the dashboard by range, brand, and tier. The contributing list shows ticket ID, tier, channel group, AI agent, brand, and timestamp. Open the ticket or AI-agent conversation from the row when you need to understand an outlier.
Tickets include Resolution type, Resolution tier, and Channel group fields. The event log records when an automated resolution occurred. These are the basis for an audit: a ticket sample tells you whether a sudden tier shift reflects a policy change, a new customer need, a channel change, or a reporting misunderstanding.
A practical review rhythm
- Fix the date range, brands, and channels before exporting.
- Record AR%, tier counts, usage, and assisted escalations.
- Pull a small sample from each material movement, including tickets that surprise you.
- Write one evidence-backed hypothesis, such as “new billing questions are becoming assisted escalations.”
- Assign one bounded response: update a source, change routing, or leave the rule alone and inspect again next week.
Do not borrow Zendesk’s tiering, performance, or billing numbers as eesel results. They describe Zendesk’s reporting. The same discipline applies to an eesel deployment: measure the actual configured teammate and its evidence.
Use eesel CLI to prepare a scoped audit, not alter Zendesk data
The eesel CLI lets a person, script, Claude Code, Codex, or Cursor operate the same eesel teammate and workspace as the dashboard. It returns JSON and does not configure Zendesk analytics.
When the scorecard shows more assisted escalations, have a coding agent help investigate a small, approved sample of de-identified cases rather than simply recomputing the total. Ask the eesel teammate to distinguish missing knowledge from an intentional human-only policy. Review connected actions and restrict those outside the analysis before supplying any file or sending a test:
npx @eesel/cli --agent "Support" instructions
npx @eesel/cli --agent "Support" files upload ./approved-handoff-sample.csv
npx @eesel/cli --agent "Support" chat "Review the uploaded handoff sample. Separate missing information from required human review, and flag cases where the record is insufficient."
The coding agent can turn the JSON into a short review list with supporting case references. For example, installation questions may lack a current guide while access disputes correctly require a person. The support owner checks the classifications against Zendesk, approves any source or instruction change for the eesel teammate, and reruns representative cases before accepting it. Preview writes with --dry-run; review activity and the receiving tickets after tests. A sample explains possible causes, not the whole population or an automated-resolution rate. Node.js 18.17+ is required.
Turn a metric review into useful support work
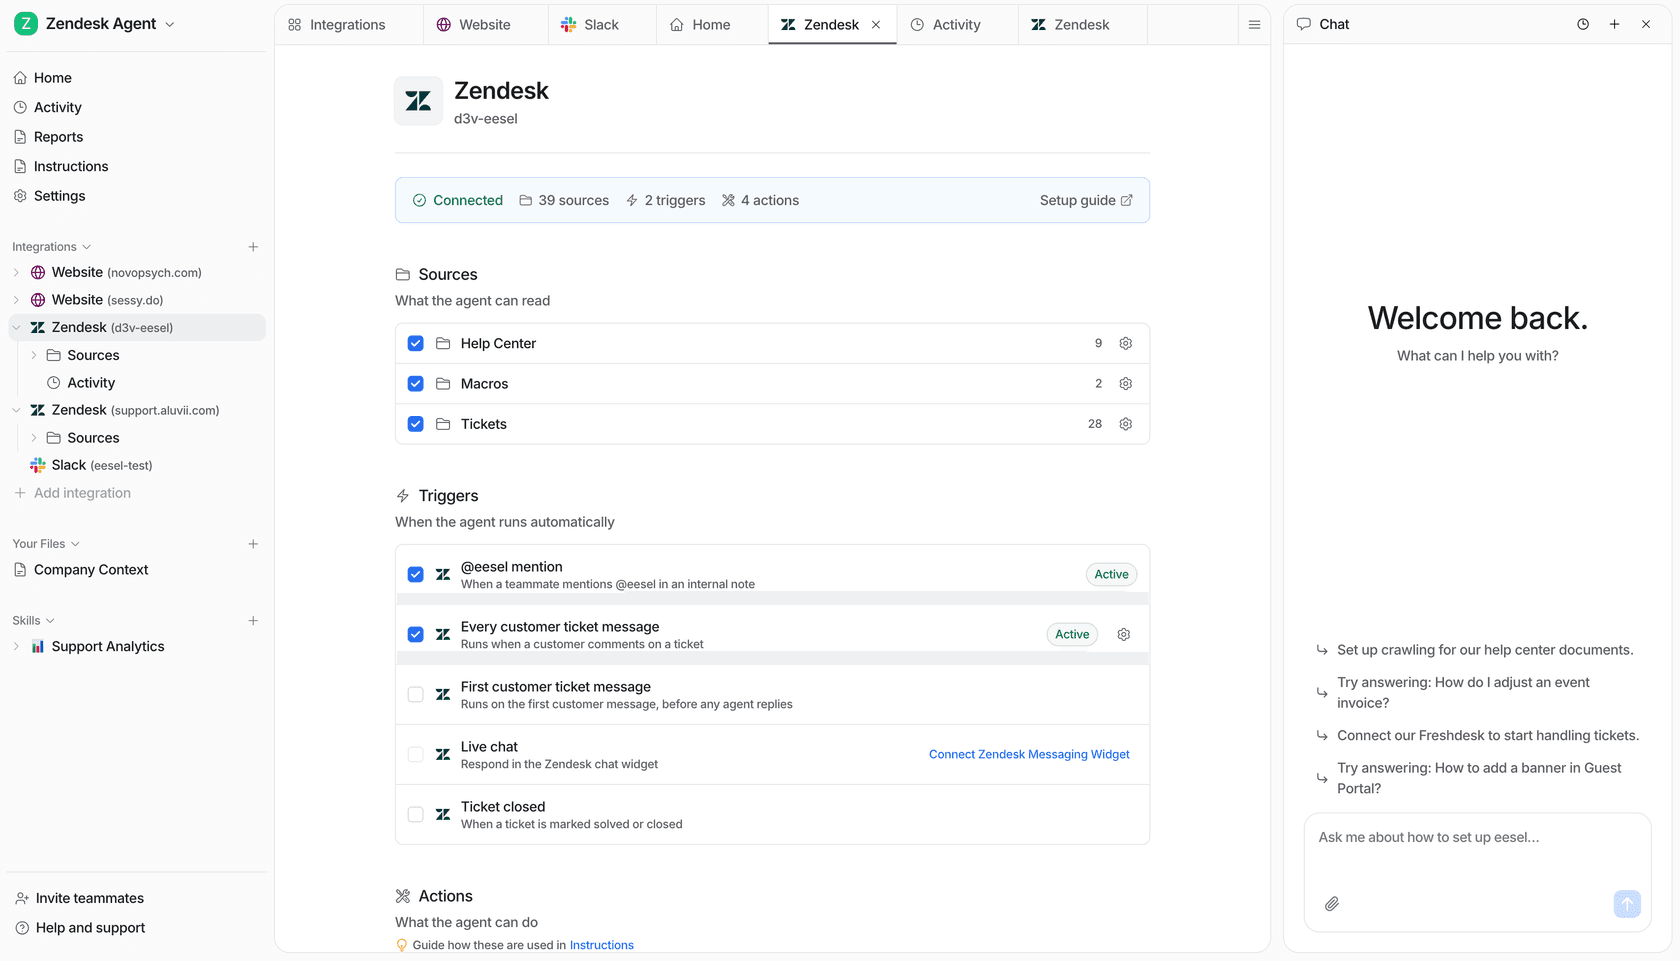
Try eesel alongside Zendesk when you want support analysis to begin with visible inputs, permissions, and evidence. Try eesel.
Frequently asked questions
Which Zendesk AI metrics should I track?
Track the resolution-tier mix, AR%, assisted escalations, channel group, usage against allowance, and a sample of underlying tickets. Each answers a different operational question.
Does Zendesk AR% include contained resolutions?
Yes. Since May 18, 2026, AR% includes contained and verified resolutions. Only verified resolutions consume automated-resolution usage.
Where is Zendesk resolution usage?
For accounts on resolution allowances, admins can open Admin Center > Account > Usage > Resolutions and filter by range, brand, and tier.
What can I export from Zendesk resolution usage?
The contributing-resolutions export includes ticket ID, tier, channel group, brand, timestamp, and cost for the chosen range and view.
Why sample tickets behind AI metrics?
A total cannot show whether a tier or routing outcome makes operational sense. Zendesk links contributing resolutions to the ticket and AI-agent conversation for this review.
How can eesel CLI help investigate a metric change?
A coding agent can upload an approved de-identified handoff sample, ask the eesel teammate to flag missing knowledge versus required human review, and prepare findings for the support owner. Verify each classification against the original ticket before changing anything.